AI Roleplay for Corporate Training: What It Is, How It Works, and Where It Actually Pays Off
AI roleplay for corporate training lets employees rehearse real work conversations with scored AI personas. Here's how enterprise simulation differs from consumer chatbots, and where it delivers ROI.
Roleplays Team
You budgeted for training, ran the workshops, assigned the mentors. Three months later your new rep still freezes on the pricing objection, your new agent still reads the compliance disclosure like a hostage note, and you still cannot prove to the CFO that any of it changed behavior. Sound familiar?
That gap is why “AI roleplay” keeps showing up in L&D conversations. The problem is that the term means two completely different things depending on who is searching.
TL;DR AI roleplay for corporate training is a simulated conversation where an employee practices a real work scenario against an AI persona by voice, video, or chat, and gets scored against a competency rubric with an auditable record. It is not the same thing as consumer character chat apps. It pays off most where conversation volume is high and coaching capacity is scarce: contact centers, collections, field sales, onboarding, and regulated compliance.
Consumer AI roleplay vs enterprise AI roleplay: two different products
Search “AI roleplay” and most results are consumer apps: character chat, companion bots, fandom personas, open-ended fiction. The design goal there is engagement. There is no rubric, no scoring, no manager visibility, and no reason for any of that to exist. The user is the customer and the conversation is the product.
Enterprise AI roleplay, sometimes called AI role play training or AI simulation training, has the opposite design goal. The conversation is disposable; the evidence is the product. A collections agent practices a hardship call with a stressed debtor persona, an HR business partner rehearses a performance conversation, a bank advisor runs a suitability discussion. Each session is configured against a scenario, scored against explicit criteria, and stored so a manager, an auditor, or a quality lead can review it later. If the platform cannot show you why a session scored the way it did, you bought a chatbot, not a training system.
How an enterprise AI roleplay session actually works, end to end
Here is the real sequence, without the marketing gloss.
Scenario configuration. Someone in L&D or enablement defines the situation: the account, the product, the customer’s mood, the objection that has to appear, the constraint the employee must respect (never promise a delivery date, always read the disclosure). Good platforms let you build this from a playbook you already have instead of writing prompts from scratch.
Persona. The AI plays a specific person, not “a customer.” Impatient SMB owner who has already been transferred twice. Nurse who is skeptical of a new formulation. Employee receiving negative feedback for the first time. Persona depth is what makes practice uncomfortable enough to be useful.
Voice interaction. The employee talks. Real speech, real interruptions, real silence to fill. Text-only practice is fine for reasoning through a framework, but it will not train the thing that actually breaks in production: what you say in the two seconds after someone pushes back. Video adds body language and presence, which matters for leadership and field-facing roles.
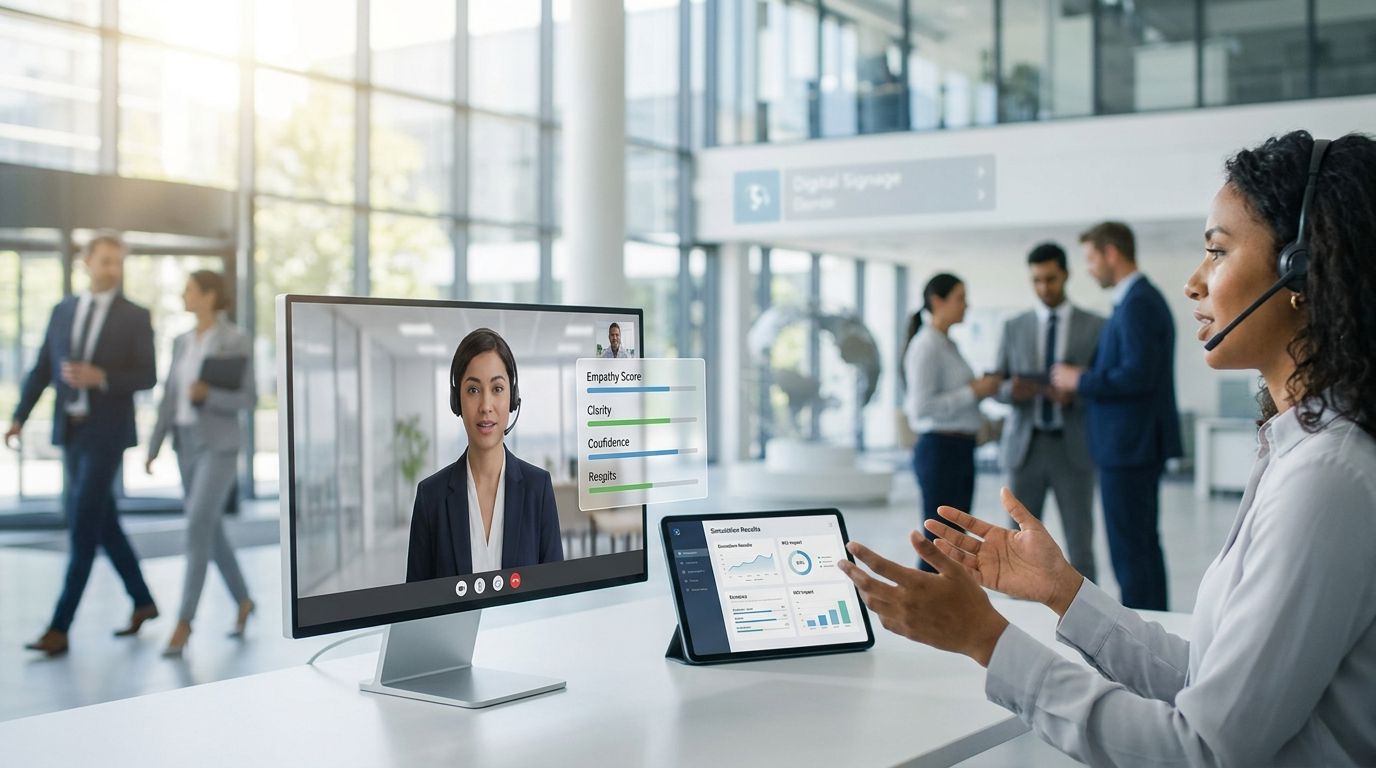
Rubric scoring. This is where enterprise and consumer diverge for good. The session is evaluated against a competency framework: discovery quality, objection handling, empathy signals, mandatory disclosures, next-step commitment. Each criterion gets a score plus the transcript evidence that produced it.
Instant feedback. The employee sees, within seconds of hanging up, what they missed and where. Not a grade. A specific line: “The customer raised budget twice and you moved to close both times without acknowledging it.”
Manager dashboard. Aggregate view by team, competency, and scenario. The useful question is not “who scored highest” but “which competency is weak across 40 people,” because that is a coaching or content problem, not an individual one.
Not just sales: where AI roleplay for business is actually deployed
The market talks about sales roleplay because that is where the first tools were built, and it is still the easiest place to see the mechanics in action if you want scripts and examples of a scored sales session. That is a small slice of the real footprint, and the department-by-department view of what it takes to train managers, support, collections and back-office teams shows where the costlier conversations actually sit.
Customer support and contact centers. New agents practice against 20 escalating scenarios before touching a live customer. High attrition environments get the most obvious return here, because you are re-running ramp-up constantly, and simulation is one of the few formats that lets you train agents without pulling them off the floor.
Collections. Hardship conversations, payment negotiation, and the tone line between firm and abusive. Also one of the most heavily regulated conversation types, which makes recorded practice valuable on its own.
HR and people management. Performance conversations, terminations, harassment complaint intake, return-to-work discussions. These are low-frequency, high-consequence conversations, exactly the kind humans never get enough reps in.
Leadership. Delegation, feedback, conflict between two reports, communicating an unpopular decision. Simulation lets first-time managers fail privately.
Compliance. Disclosure delivery, suitability questioning, adverse event capture in pharma, data handling under privacy rules. In banking this gets very concrete: KYC and AML training built on realistic compliance simulations puts the analyst in front of an evasive customer instead of a slide deck. In Europe the same expectation now reaches AI use itself, since Article 4 of the EU AI Act asks employers to evidence sufficient AI literacy role by role without prescribing any curriculum. Compliance training nobody remembers is compliance theater. A recorded practice session where the employee actually said the required thing is a materially different artifact than a completed e-learning checkbox.
Field service and back office. On-site expectation setting, upsell conversations at the customer’s kitchen table, internal handoffs, supplier calls. Less glamorous, high volume, rarely coached at all.
What it can measure, and what it cannot
Being honest here saves you a painful renewal conversation.
It measures well: adherence to a defined process, whether mandatory elements appeared, question quality and ratio, structure of discovery, handling of a specific objection, clarity, pacing, tone consistency, and improvement across repeated attempts. It measures these consistently, which is its real advantage over human roleplay, where two supervisors score the same call differently. The retention side of that comparison is worth reading on its own, because the data on AI role-play versus traditional sales training is less flattering to the classroom than most L&D budgets assume.
It measures poorly or not at all: whether the employee will actually behave this way under real pressure, relationship-building over months, judgment in genuinely novel situations, and cultural nuance that was never encoded in the rubric. Scores are a proxy for readiness, not proof of it.
And the honest caveat: AI roleplay does not replace manager coaching. It removes the mechanical reps from the manager’s plate so the coaching that happens is aimed at the five people who need it, with transcript evidence attached.
Buying criteria that separate real platforms from demos
| Criterion | What to test | Red flag |
|---|---|---|
| Scenario configurability | Can you build a non-sales scenario (collections, HR, compliance) yourself in under an hour? | Only sales templates exist |
| Voice quality and latency | Does the persona interrupt, pause, and respond fast enough to feel like a call? | Noticeable lag, robotic turn-taking |
| Rubric control | Can you edit criteria, weights, and pass thresholds, and reuse them across departments? | Fixed, vendor-defined scoring |
| Multimodality | Voice, video, and chat in the same competency framework | Chat-only dressed up as simulation |
| SSO and data residency | SAML/SCIM, defined storage region, retention controls | Vague answers about where recordings live |
| Evidence trail | Exportable session record with transcript, score, criterion, and timestamp | Scores with no supporting evidence |
Ask every vendor the same question: show me a scored session from a department that is not sales. The demos that fall apart, fall apart right there.
A realistic 90-day rollout for 1,000+ employees
Days 1 to 30, prove it on one team. Pick a single high-volume role, ideally one with measurable downstream metrics. Build 5 to 8 scenarios and one competency rubric with the people who actually coach that role. Run 30 to 50 employees. Do not integrate anything yet.
Days 31 to 60, harden and connect. Turn on SSO, confirm data residency, calibrate the rubric against 20 sessions that human supervisors also score, and fix the gaps. Calibration is the step everyone skips and everyone regrets. Then wire results into your LMS or enablement stack and train managers to read the dashboard.
Days 61 to 90, expand by competency, not by headcount. Reuse the same competency framework in a second department. If your “empathy under pressure” criteria work for support, they largely work for collections and HR. That reuse is where the economics improve, because scenario building, not licensing, is the real cost of scale.
Target for day 90: two departments live, one calibrated rubric library, and a defensible before/after comparison on one operational metric. Decide up front which numbers you will defend, ideally against an explicit ROI measurement framework for AI-powered training programs, because retrofitting the baseline after the pilot is how programs lose their budget.
FAQ
What is AI roleplay? AI roleplay is a simulated conversation where a person practices a real scenario against an AI-played persona. In corporate training, the session is scored against a competency rubric and recorded as evidence. In consumer apps, it is open-ended character chat with no evaluation layer.
Is AI roleplay effective for training? It is effective for skills that depend on repetition and consistent feedback: objection handling, disclosure delivery, discovery questioning, difficult conversations. The mechanism is deliberate practice, which is well established in the learning literature. It is less effective for judgment in novel situations, and it does not replace manager coaching.
How much does AI roleplay for business cost? Pricing is typically per seat per year, tiered by voice/video usage and scenario volume, with a separate implementation or scenario-build component. Cost varies widely by vendor and modality, so evaluate total cost including scenario authoring, not just license price. Ask for pricing at 100, 500, and 2,000 seats before you commit.
Is AI roleplay safe for regulated industries? It can be, if the platform supports SSO, defined data residency, retention and deletion controls, and an exportable evidence trail linking each score to the transcript that produced it. Practice sessions should use synthetic scenarios rather than real customer data. Validate the audit export format with your compliance team before procurement, not after.
Ready to see a scored session in your own scenario? Book a demo and bring your hardest conversation.
Stay in the loop
Get the latest insights on corporate training delivered to your inbox.